Publications
For a complete list, see Google Scholar.
2026
-
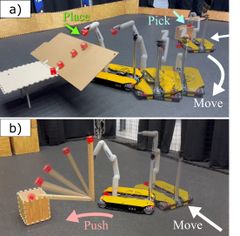
J1 Cross-Entropy Optimization of Physically Grounded Task and Motion Plans
IEEE Robotics and Automation Letters (RA-L), presented at IROS 2026, 2026
pdf paper arxiv website code poster
Autonomously performing tasks often requires robots to plan high-level discrete actions and continuous low-level motions to realize them. Task and Motion Planning (TAMP) algorithms solve these hybrid problems together. Previous TAMP algorithms have focused mainly on computational performance, completeness, or optimality by making the problem tractable through simplifications and abstractions. However, this comes at the cost that the resulting plans may not adequately account for the dynamics or complex contacts necessary to reliably perform the task when manipulation of objects is required. Additionally, approaches that ignore effects of the low-level controllers may not obtain optimal or feasible plan realizations for the real system. We investigate the use of a GPU-parallelized physics simulator to compute realizations of plans with a motion controller, explicitly accounting for dynamics, and considering contacts with the environment. Using cross-entropy optimization, we sample the parameters of the controllers, or actions, to obtain low-cost solutions. Since our approach uses the same controllers as the real system, the robot can directly execute the computed plans. We demonstrate our approach for a set of tasks where the robot is able to exploit the environment's geometry to move an object.
@article{matoses2026crossentropy, title = {Cross-Entropy Optimization of Physically Grounded Task and Motion Plans}, author = {Matoses Gimenez, Andreu and Wilde, Nils and Pek, Chris and Alonso-Mora, Javier}, journal = {IEEE Robotics and Automation Letters}, year = {2026}, month = mar, url = {https://ieeexplore.ieee.org/document/11486591}, eprint = {2512.11571}, archiveprefix = {arXiv} } -
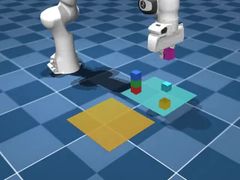
P2 Flow Policies as Actions of Skill-Level World Models: Learned and Symbolic Abstractions for Long-Horizon Planning
arXiv preprint, submitted to ICRA 2027, 2026
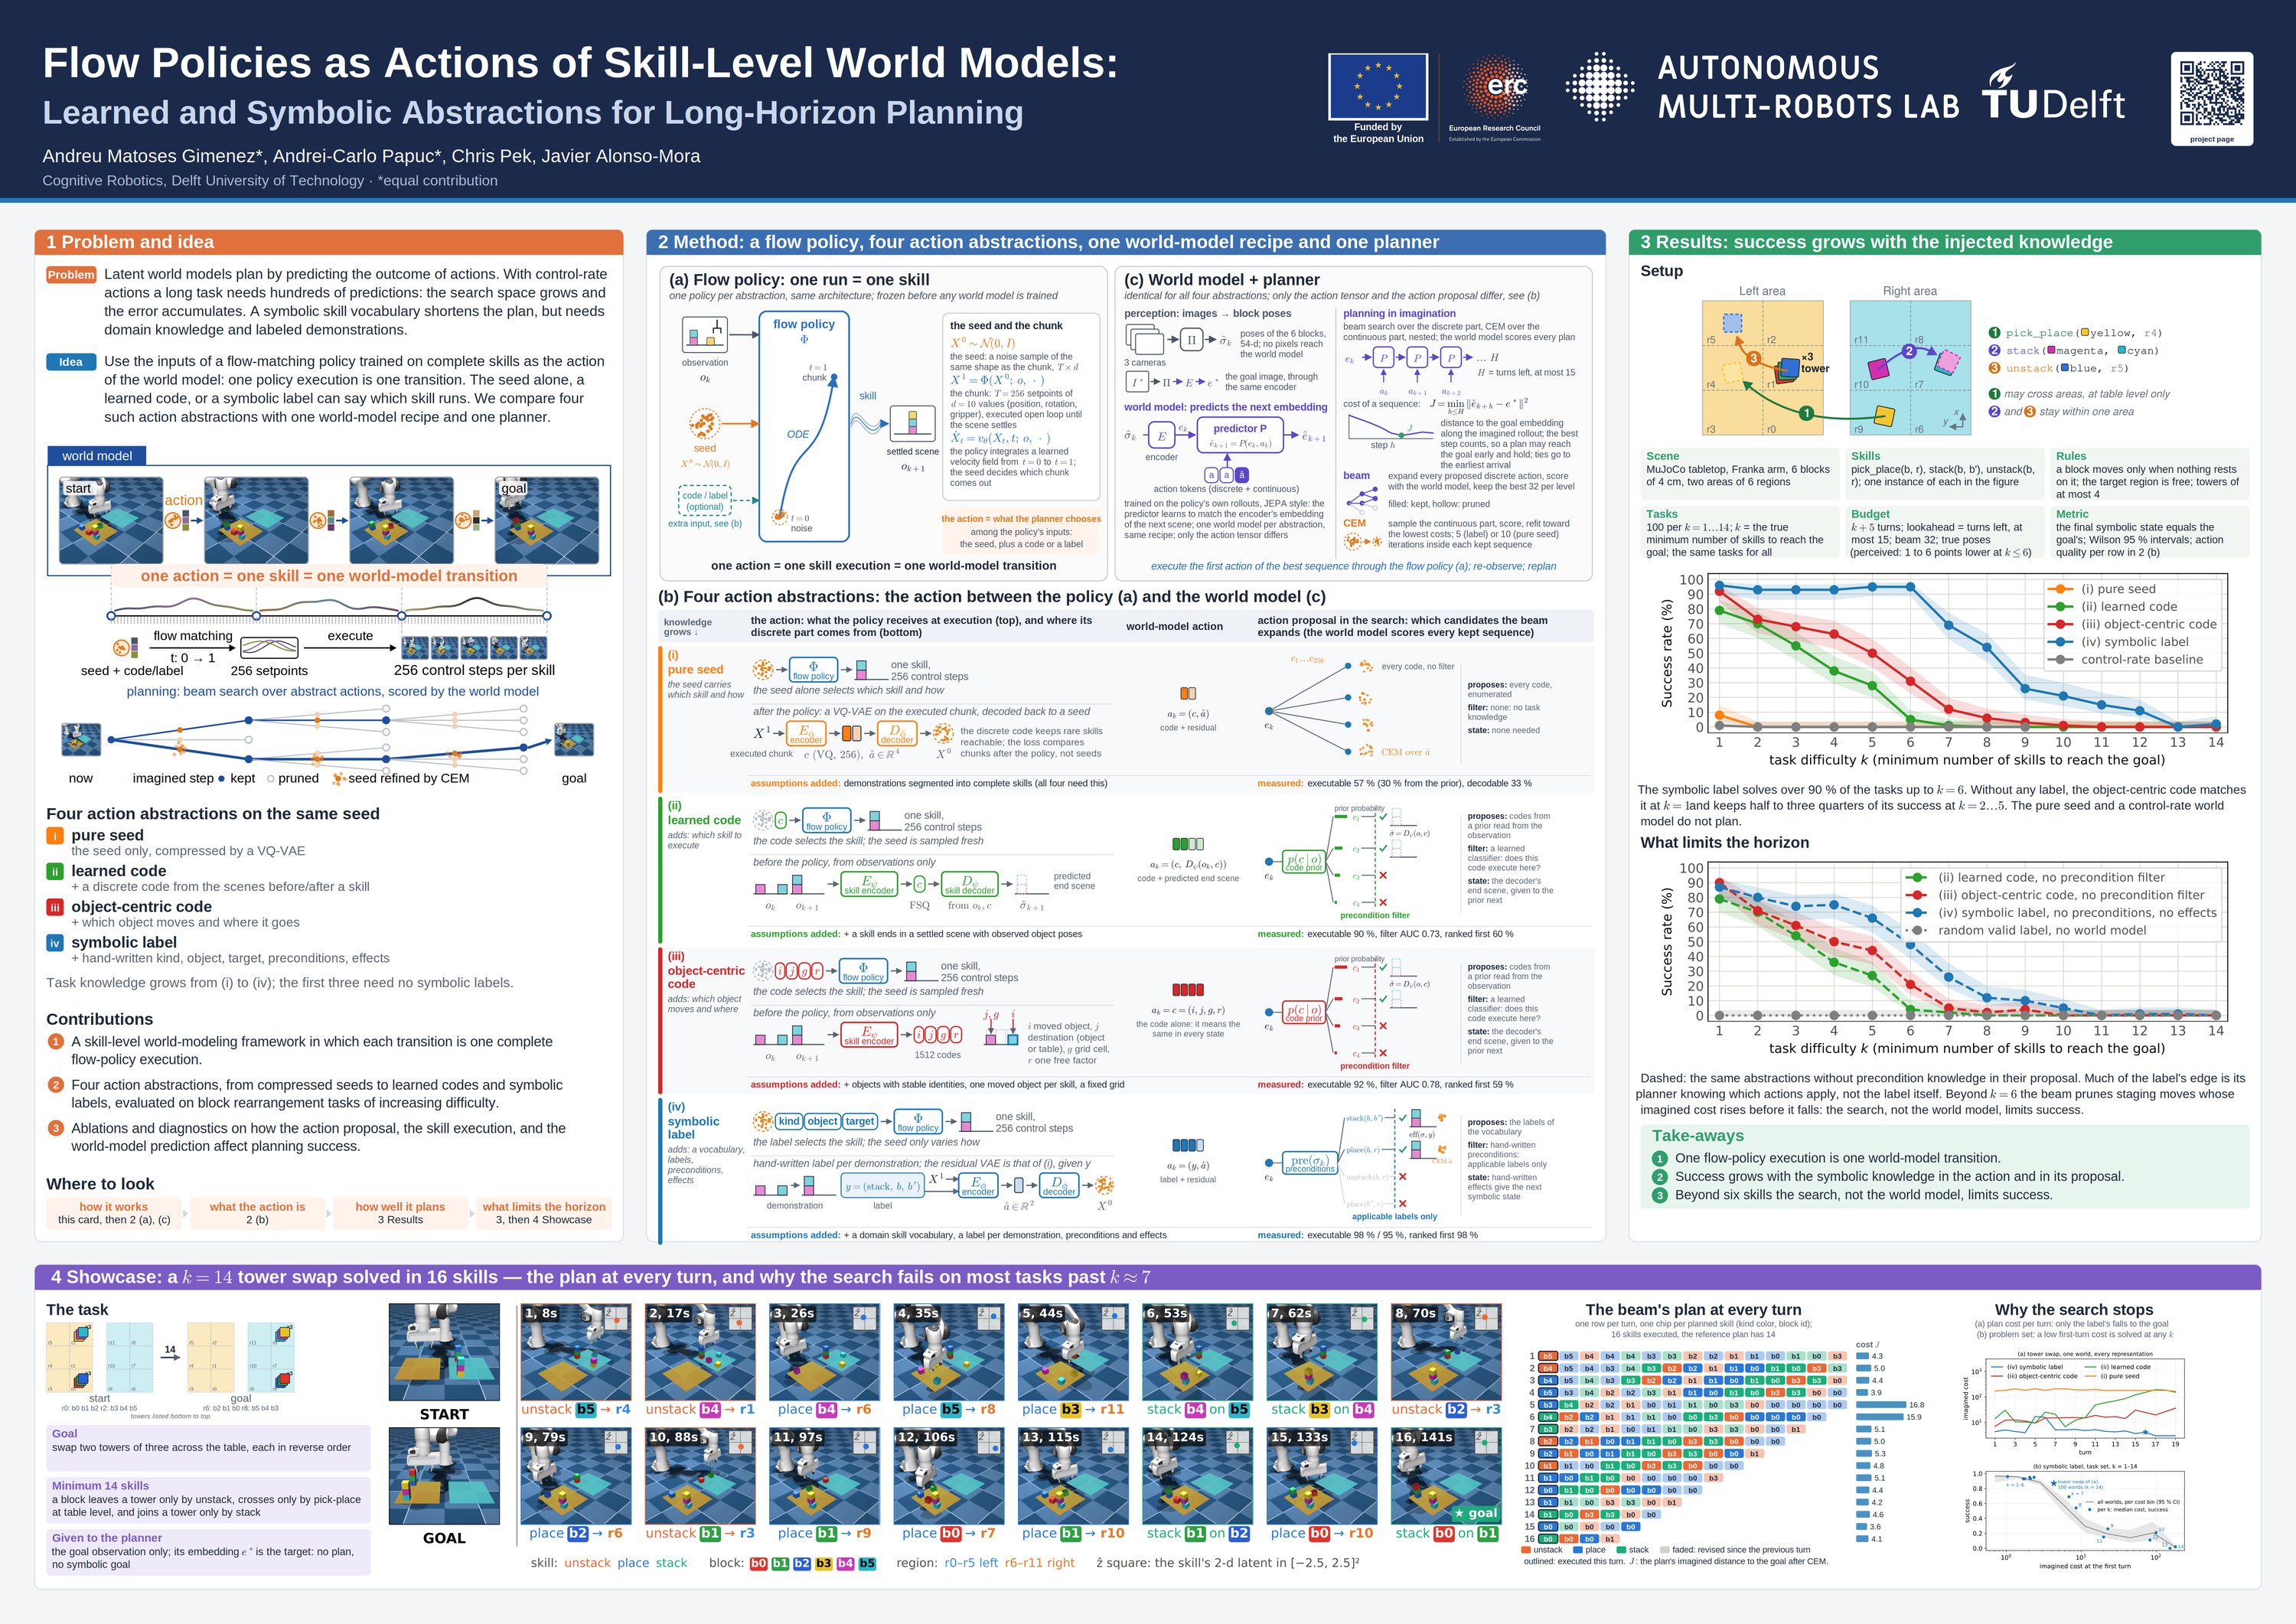
Latent world models enable robots to plan by predicting the consequences of actions. Planning long tasks with control-rate actions requires many prediction steps, which enlarges the search space and accumulates error. Skill-level actions shorten these sequences, but a symbolic skill vocabulary requires domain knowledge and labeled demonstrations. We construct skill-level actions from the inputs of a flow-matching policy trained on demonstrations segmented into complete skills. The policy maps a noise seed and an observation, optionally with a code or label, to a complete skill execution, so one execution is one world-model transition. On this mechanism we propose four action abstractions with increasing task knowledge: a compressed seed, two discrete codes learned from the demonstrations, and a symbolic label. We evaluate them with a common world-model training procedure and planning framework on simulated block rearrangement tasks that require up to 14 sequential skills. The symbolic label succeeds in over 90% of the tasks that require up to six skills and degrades beyond. Without any label, an object-centric learned code matches it on single-skill tasks and retains half to three quarters of its success on tasks of two to five skills. Ablations attribute much of the label's advantage to its planner knowing which actions are applicable, rather than to the label itself. Beyond six skills the search, not the world model, limits success. Project page: https://andreumatoses.github.io/research/flow-skill-wm
@misc{matoses2026flowskillwm, title = {Flow Policies as Actions of Skill-Level World Models: Learned and Symbolic Abstractions for Long-Horizon Planning}, author = {Matoses Gimenez, Andreu and Papuc, Andrei-Carlo and Pek, Chris and Alonso-Mora, Javier}, year = {2026}, month = oct, eprint = {2610.04767}, archiveprefix = {arXiv}, primaryclass = {cs.RO}, url = {https://arxiv.org/abs/2610.04767} } -
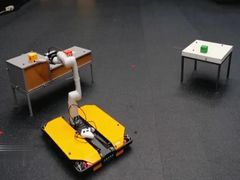
P1 Learning Task and Motion Plans from Real Demonstrations with Hybrid Flow Matching
arXiv preprint, submitted to ICRA 2027, 2026
Long-horizon mobile manipulation requires a task plan and the motion that executes it. Generative planners trained on demonstration produce both in one pass, requiring neither a symbolic domain nor search. To date, however, they have relied on thousands of scripted demonstrations of fixed-base arms and executed open loop. This paper presents a hybrid flow matching planner: a single network generates the symbolic plan with masked discrete flow matching and the motion trajectory with continuous flow matching. Unlike prior generative planners, we aim to learn from a much smaller set of demonstrations and to execute the plan in closed loop. Two properties of the data compensate for the small dataset. A demonstration resumed from any of its intermediate actions is itself a demonstration, which multiplies the training samples and enables replanning after every action. Objects of the same kind are interchangeable, which turns demonstrations of one goal into demonstrations of every permuted goal. Our base implementation produces valid plans on 68% of held-out scenes; a training and generation scheme for the discrete plan raises this to 76%, and replanning after every action raises the task completion rate from 40% to 53% in a kinematic simulation. The planner matches the task completion rate of motion-only flow matching policies while additionally providing the symbolic plan, and it outperforms previous hybrid diffusion formulations on both task completion and plan validity. We validate the planner on a real mobile manipulator. Videos and project page: https://andreumatoses.github.io/research/hybrid-flow-planning
@misc{redondo2026hybridflow,
  title         = {Learning Task and Motion Plans from Real Demonstrations with Hybrid Flow Matching},
  author        = {Redondo Garcia, Zuleika and Matoses Gimenez, Andreu and Alonso-Mora, Javier},
  year          = {2026},
  month         = oct,
  eprint        = {2610.04771},
  archiveprefix = {arXiv},
  primaryclass  = {cs.RO},
  url           = {https://arxiv.org/abs/2610.04771}
}
2025
-
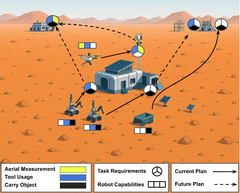
C4 SADCHER: Scheduling using Attention-based Dynamic Coalitions of Heterogeneous Robots in Real-Time
IEEE Int. Symposium on Multi-Robot & Multi-Agent Systems (MRS), 2025
Multi-robot task allocation in heterogeneous systems requires efficient scheduling methods that can handle dynamic environments and diverse robot capabilities. This paper presents SADCHER, a novel attention-based approach for scheduling dynamic coalitions of heterogeneous robots in real-time. Our method leverages deep reinforcement learning and attention mechanisms to enable scalable and adaptive task assignment across robot teams with varying capabilities. The approach is validated through extensive simulations and demonstrates significant improvements in task completion rates and system efficiency compared to baseline methods.
@inproceedings{bichler2025sadcher, title = {{SADCHER}: Scheduling using Attention-based Dynamic Coalitions of Heterogeneous Robots in Real-Time}, author = {Bichler, Jakob and Matoses Gimenez, Andreu and Alonso-Mora, Javier}, booktitle = {IEEE International Symposium on Multi-Robot and Multi-Agent Systems (MRS)}, year = {2025}, month = oct, eprint = {2510.14851}, archiveprefix = {arXiv} } -
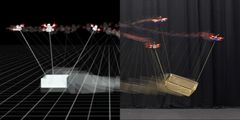
C3 Decentralized Aerial Manipulation of a Cable-Suspended Load Using Multi-Agent Reinforcement Learning
Conference on Robot Learning (CoRL), 2025
paper arxiv website code video
This paper presents the first decentralized method to enable real-world 6-DoF manipulation of a cable-suspended load using a team of Micro-Aerial Vehicles (MAVs). Our method leverages multi-agent reinforcement learning (MARL) to train an outer-loop control policy for each MAV. Unlike state-of-the-art controllers that utilize a centralized scheme, our policy does not require global states, inter-MAV communications, nor neighboring MAV information. Instead, agents communicate implicitly through load pose observations alone, which enables high scalability and flexibility. It also significantly reduces computing costs during inference time, enabling onboard deployment of the policy. In addition, we introduce a new action space design for the MAVs using linear acceleration and body rates. This choice, combined with a robust low-level controller, enables reliable sim-to-real transfer despite significant uncertainties caused by cable tension during dynamic 3D motion. We validate our method in various real-world experiments, including full-pose control under load model uncertainties, showing setpoint tracking performance comparable to the state-of-the-art centralized method. We also demonstrate cooperation amongst agents with heterogeneous control policies, and robustness to the complete in-flight loss of one MAV.
@inproceedings{zeng2025aerialmarl,
  title         = {Decentralized Aerial Manipulation of a Cable-Suspended Load Using Multi-Agent Reinforcement Learning},
  author        = {Zeng, Jack and Matoses Gimenez, Andreu and Vinitsky, Eugene and Alonso-Mora, Javier and Sun, Sihao},
  booktitle     = {Conference on Robot Learning (CoRL)},
  year          = {2025},
  month         = aug,
  url           = {https://proceedings.mlr.press/v305/zeng25a.html},
  eprint        = {2508.01522},
  archiveprefix = {arXiv}
}
2024
-
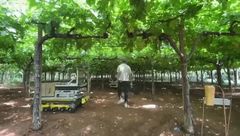
C2 Enhancing Precision Agriculture through Human-In-The-Loop Planning and Control
IEEE 20th International Conference on Automation Science and Engineering (CASE), 2024
In this paper, we introduce a ROS based framework designed for the planning and control of robotic systems within the context of precision agriculture, with an emphasis on human-in-the-loop capabilities. Utilizing Linear Temporal Logic to articulate complex task specifications, our algorithm creates high-level robotic plans that are not only correct by design but also adaptable in real time by human operators. This dual-focus approach ensures that while humans have the flexibility to modify the high-level plan on-the-fly or even take over low-level control of the robots, the system inherently safeguards against any human actions that could potentially breach the predefined task specifications. We demonstrate our algorithm within the dynamic and challenging environment of a real vineyard, where the collaboration between human workers and robots is critical for tasks such as harvesting and pruning, and show the practical applicability and robustness of our software. This work marks a pioneering application of formal methods to complex, real-world agricultural environments.
@inproceedings{deka2024canopies, title = {Enhancing Precision Agriculture through Human-In-The-Loop Planning and Control}, author = {Deka, Shankar and Phodapol, Sujet and Matoses Gimenez, Andreu and Fernandez-Ayala, Victor Nan and Wong, Rufus C. Y. and Yu, Pian and Tan, Xiao and Dimarogonas, Dimos V.}, booktitle = {IEEE 20th International Conference on Automation Science and Engineering (CASE)}, year = {2024}, month = aug, url = {https://ieeexplore.ieee.org/abstract/document/10711319} } -
W1 Physically Grounded Optimal Realizations of Symbolic Plans
Robotics: Science and Systems (RSS), Workshop on Frontiers of Optimization for Robotics, 2024
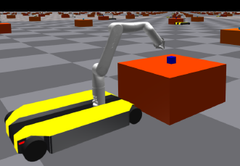
Robot autonomy often involves planning high-level discrete decisions and continuous motion planning to realize each decision. Task and Motion Planning (TAMP) algorithms solve these hybrid problems jointly while considering constraints between the discrete symbolic actions, i.e., the task plan, and their continuous geometric realization. Previous TAMP algorithms have mostly focused on computational performance, completeness, or optimality. However, due to the required simplifications and abstractions, the resulting plans often do not account for robot dynamics, nor complex contacts. They also often ignore the effect of the low-level controllers on the optimality and/or feasibility of the plan's realizations. This work investigates the use of a parallelized physics simulator to compute realizations of the plan with a motion controller, realistic dynamics, and considering contacts with the environment. Using cross-entropy optimization, we sample the parameters used by the controllers, or actions, to obtain low-cost solutions. The resulting realized plan is straightforward to implement in the real system, as the robot uses the same controllers. We test our approach for a pick and place task, where our method is capable of finding low-cost feasible solutions in 1-2 min.
@inproceedings{matoses2024rssworkshop,
  title     = {Physically Grounded Optimal Realizations of Symbolic Plans},
  author    = {Matoses Gimenez, Andreu and Wilde, Nils and Pek, Chris and Alonso-Mora, Javier},
  booktitle = {Robotics: Science and Systems (RSS), Workshop on Frontiers of Optimization for Robotics},
  year      = {2024},
  month     = jul
}
2023
-
T1 Scalable Reinforcement Learning for Formation Control with Collision Avoidance
Master's thesis, KTH Royal Institute of Technology, 2023
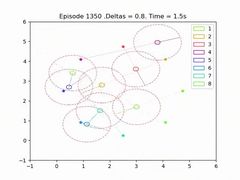
In the last decades, significant theoretical advances have been made on the field of distributed mulit-agent control theory. One of the most common systems that can be modelled as multi-agent systems are the so called formation control problems, in which a network of mobile agents is controlled to move towards a desired final formation. These problems additionally pose practical challenges, namely limited access to information about the global state of the system, which justify the use distributed and localized approaches for solving the control problem. The problem is further complicated if partial or no information is known about the dynamic model of the system. A widely used approach for model free control is reinforcement learning (RL). A fundamental challenge of this approach in this setting is that the state-action space size scales exponentially with the number of agents, rendering the problem intractable for a large networks. This thesis presents a scalable and localized reinforcement learning approach to a traditional multi-agent formation control problem, with collision avoidance. A scalable reinforcement learning advantage actor critic algorithm is presented, based on previous work in the literature. Sub-optimal bounds are calculated for the accumulated reward and policy gradient localized approximations. The algorithm is tested on a two dimensional setting, with a network of mobile agents following simple integrator dynamics and stochastic localized policies. Neural networks are used to approximate the continuous value functions and policies. The formation control with collisions avoidance formulation and the algorithm presented show good scalability properties, with a polynomial increase in the number of function approximations parameters with number of agents. The reduced number of parameters decreases learning time for bigger networks, although the efficiency of computation is decreased compared to state of the art machine learning implementations. The policies obtained achieve probably safe trajectories although the lack of dynamic model makes it impossible to guarantee safety.
@mastersthesis{matoses2023msc,
  title  = {Scalable Reinforcement Learning for Formation Control with Collision Avoidance},
  author = {Matoses Gimenez, Andreu},
  school = {KTH Royal Institute of Technology},
  year   = {2023},
  month  = feb,
  url    = {https://kth.diva-portal.org/smash/get/diva2:1750943/FULLTEXT01.pdf}
}
2022
-
C1 Design of a HALE UAV for Atmospheric Imaging
International Council of the Aeronautical Sciences (ICAS), 2022
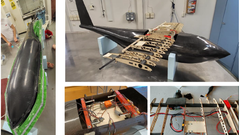
Optical phenomena in the upper atmosphere, such as northern lights, airglow, noctilucent clouds and thunderstorm-related transient luminous phenomena reveal the complex processes coupling different layers of the atmosphere and the near earth space. Bad weather and lighting conditions, as well as geographical constraints, limit the possibilities of ground based imaging. Therefore, an autonomous high altitude long endurance (HALE) fixed-wing unmanned aerial vehicle (UAV) is proposed for atmospheric imaging, as a joint student-driven research project between the Aeronautics and Vehicle Engineering- and the Space and Plasma Physics departments at KTH Royal Institute of Technology. The Autonomous Light Platform for High Altitude atmospheric imaging (ALPHA) is specifically designed for operations in the environmentally harsh conditions found in Arctic night time.
@inproceedings{fernandezayala2022alpha,
  title     = {Design of a {HALE} {UAV} for Atmospheric Imaging},
  author    = {Nan Fernandez-Ayala, Victor and Vimláti, László and Matoses Gimenez, Andreu and Delmotte, Helena and Ivchenko, Mykola and Mariani, Raffaello},
  booktitle = {33rd Congress of the International Council of the Aeronautical Sciences (ICAS)},
  address   = {Stockholm},
  year      = {2022},
  month     = sep,
  url       = {https://www.icas.org/ICAS_ARCHIVE/ICAS2022/data/papers/ICAS2022_0447_paper.pdf}
}